Tag: llama.cpp
-
The 11.8 Gigabyte 27B
A 27-billion-parameter model in an 11.8 gigabyte file, scoring the same as the 54-gigabyte original. Which size fits your card, how to run it, and why the method itself is the bigger story.
-
How to Configure OpenWork for Local AI
Here’s how you’d do this entirely through the OpenWork UI — two approaches: Method 1: Settings UI (Recommended for most users expected on Cloud App versions) Step 1 — Open AI Provider Settings In the OpenWork Cloud app (yes – the CLOUD App – we need to distinguish this early, OpenWork has two versions: a…
-
Local Doesn’t Mean Locked
Security firm Cyera found 10 vulnerabilities in llama.cpp — the engine behind Ollama, LM Studio and most local AI. Five were still unpatched at their June 2026 re-check. Here’s what they are in plain English, and what to do if you run local AI at home or in the office.
-
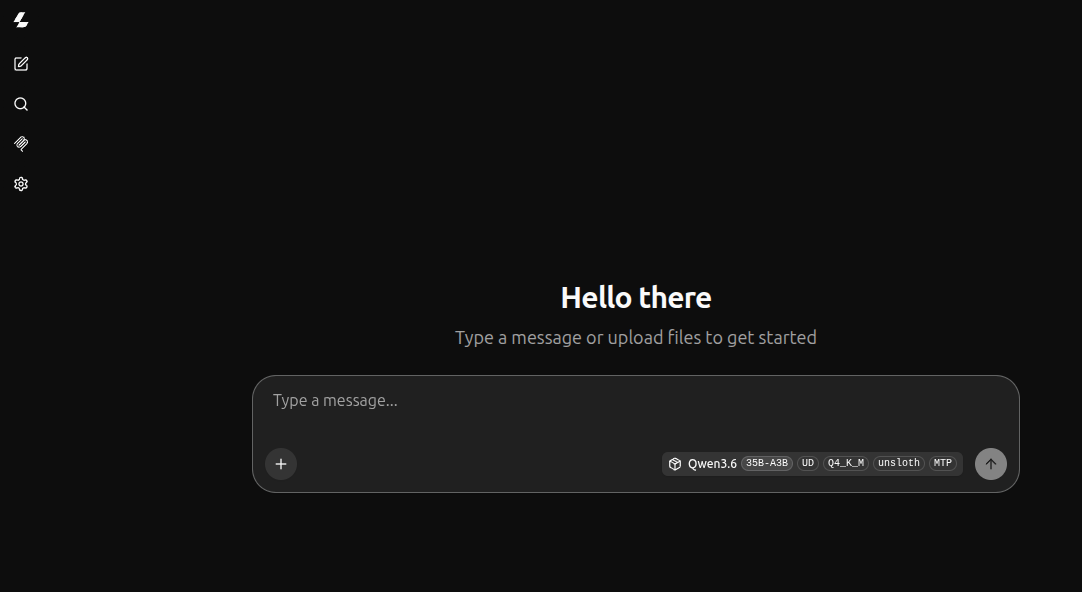
The Private Local AI Server Install
Completed my operational setup of a private Local AI Chat that can process audio, video, images, text file, PDFs and can even hook up with MCP servers. And my choice of AI model? I chose the Qwen 3.6 35B-A3B UD Q4_K_M MTP model finetuned by unsloth studio. The 35B-A3B Architecture is an MoE (Mixture of…
-
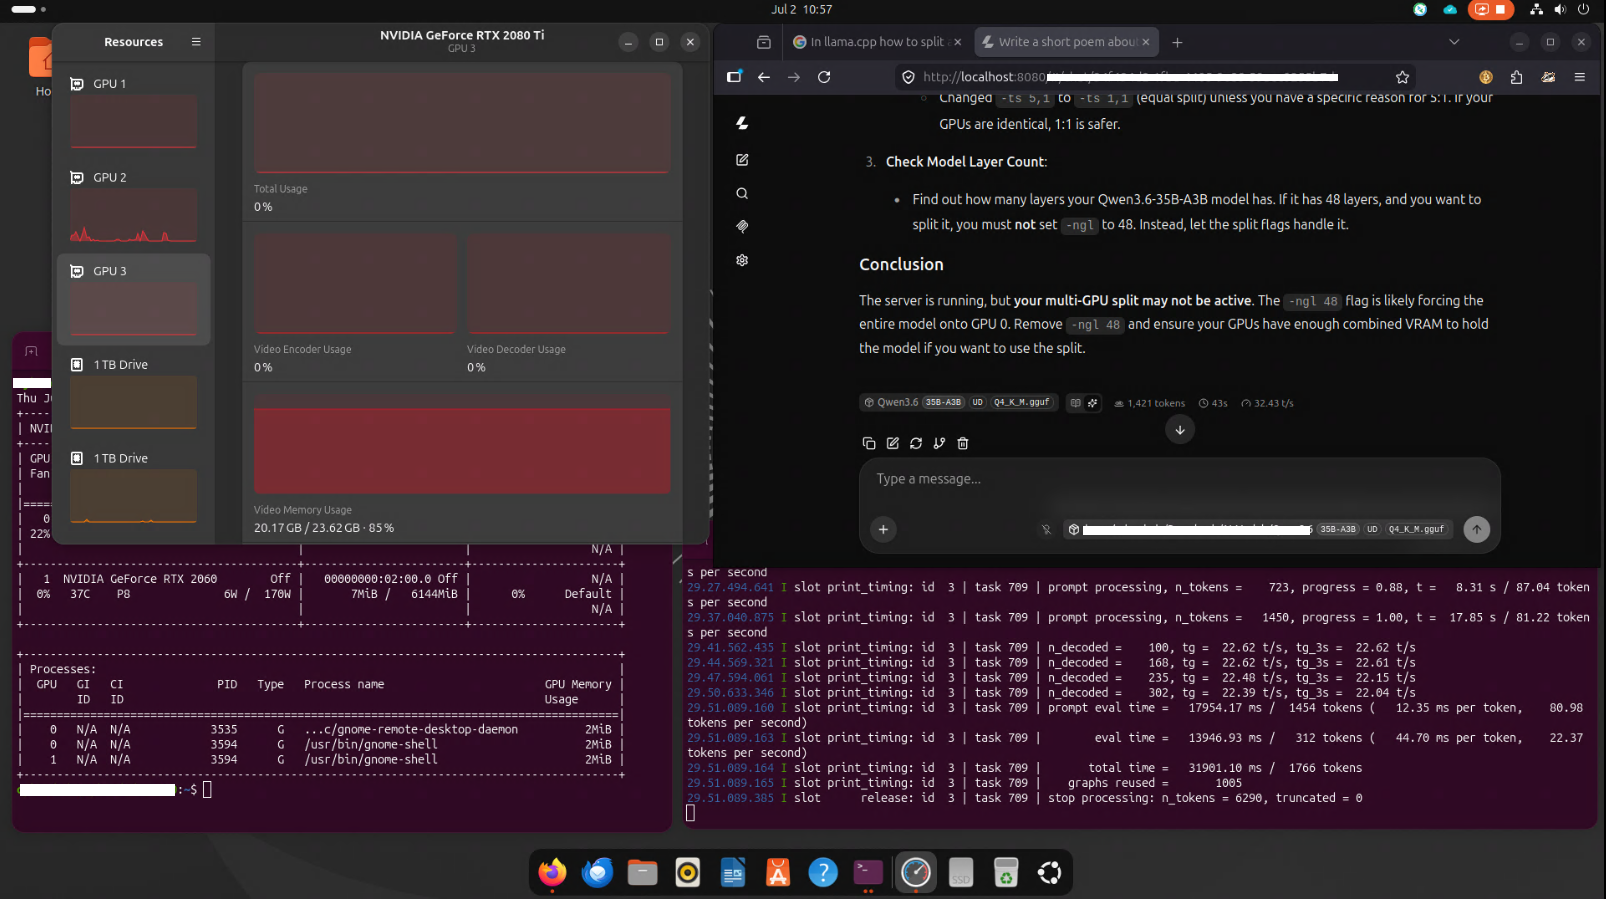
Initial Trials of A Local AI Server Testing
Jul 2, 2026 Initial performance trials for my Local AI server setup with 2 GPUs was promising, certainly with help coming from finetuning flags in Llama.cpp (big shoutout to Georgi Gerganov, luv your work!) that allows me to split up the 35B AI model into 2 GPUs with differing (6GB and 22GB) VRAMs. Utilizing a…
-
AI Guide: How to Install Llama.cpp onto your Desktop PC for Local AI
June 16th, 2026 After some weeks of research, trials and errors, I managed to successfully install Llama.cpp and have it working with my AMD GPU using vulkan instead of RoCm on Linux Mint v22.3 OS. Learnt many lessons from the experience, and happy to share that here. The next thing now would be to install…