Category: HomeLab Tech
-
Local Doesn’t Mean Locked
Security firm Cyera found 10 vulnerabilities in llama.cpp — the engine behind Ollama, LM Studio and most local AI. Five were still unpatched at their June 2026 re-check. Here’s what they are in plain English, and what to do if you run local AI at home or in the office.
-
From Chatting to Delegating: Why Professionals Should Learn OpenWork
21st Aug 2026 Let’s be honest about where most professional AI use actually lives. You’ve got ChatGPT or Claude open in a tab, you type a prompt, it hands you back text. You draft the email, it summarises the doc, you brainstorm, it throws out an idea. Useful. But it’s still a chatbot. It talks…
-
OpenWork: The Claude Cowork Alternative
Aug 18th, 2026 I Pointed an AI at My Homelab. Setup Was One Line. It Still Hasn’t Broken Anything. Every AI app is an island. You connect your Google account in one, teach it a skill in another, and the moment you switch apps, you’re back to square one. For most people that’s an annoyance.…
-
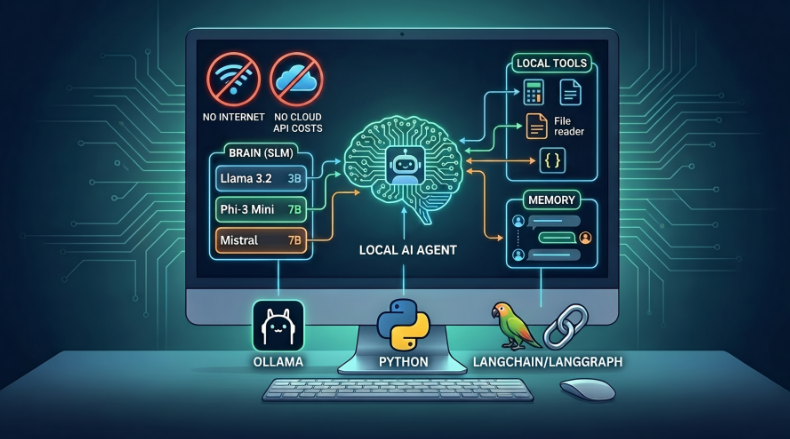
The Great AI Showdown: Why Ditch Google’s “Flash” for Qwen as your Local Agent
Jul 24th, 2026 Let’s be honest: I have a bit of a love-hate relationship with Google’s new AI Mode. On one hand, it’s free. On the other hand, it’s a black box. I use it constantly for those “hey, how does this tech thing work?” questions that don’t involve my bank password or my pet’s…
-
The Private Local AI Server Install
Completed my operational setup of a private Local AI Chat that can process audio, video, images, text file, PDFs and can even hook up with MCP servers. And my choice of AI model? I chose the Qwen 3.6 35B-A3B UD Q4_K_M MTP model finetuned by unsloth studio. The 35B-A3B Architecture is an MoE (Mixture of…
-
Initial Trials of A Local AI Server Testing
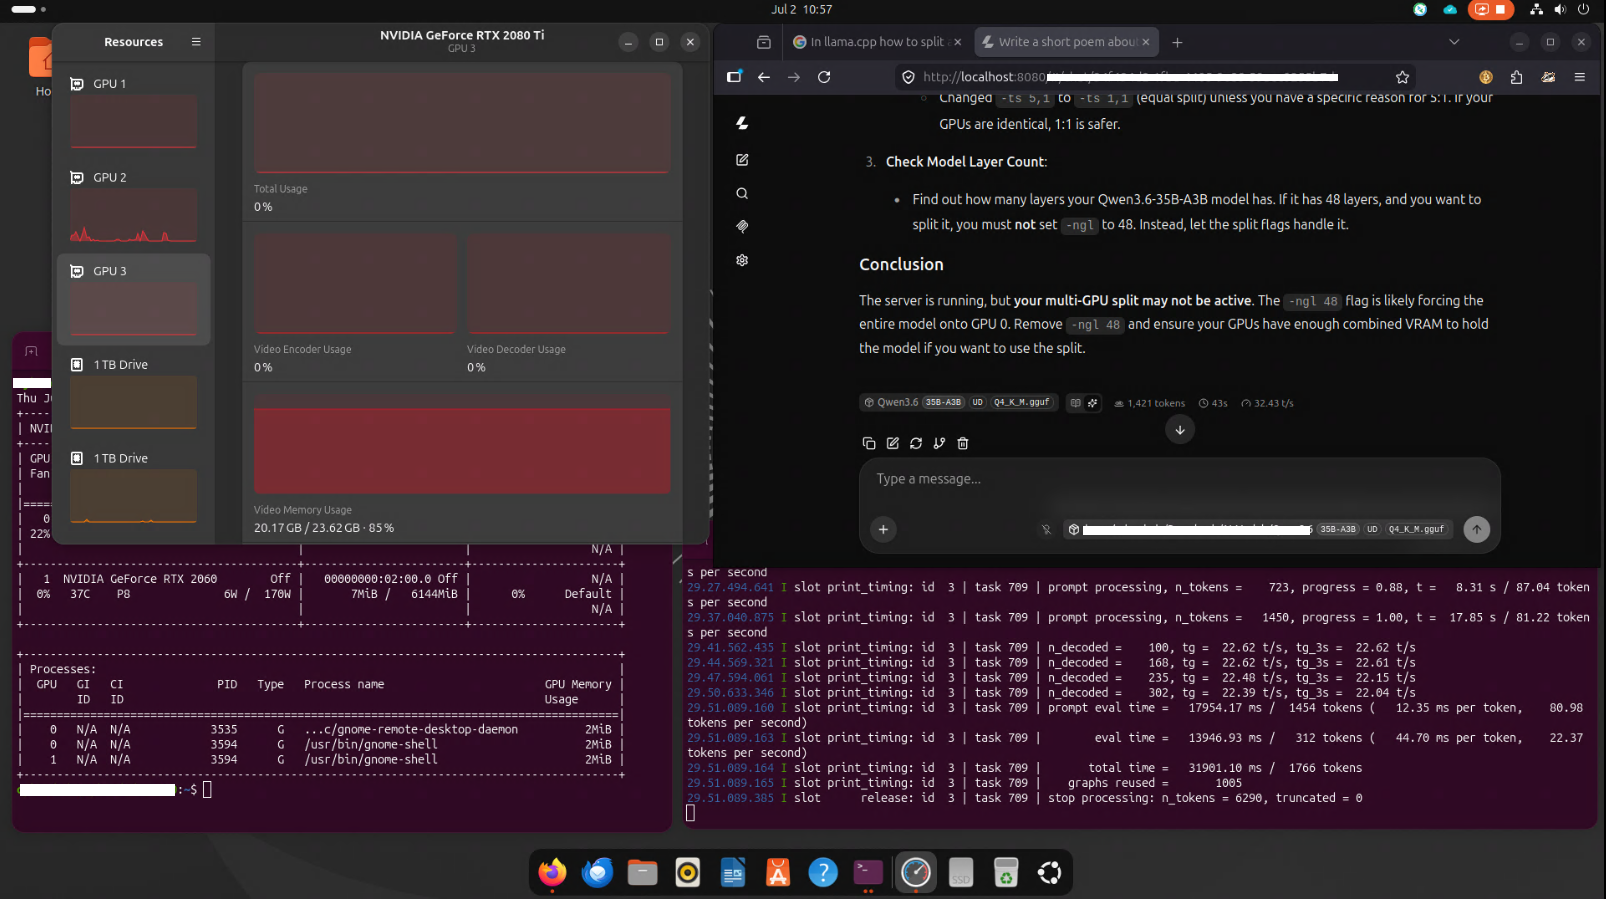
Jul 2, 2026 Initial performance trials for my Local AI server setup with 2 GPUs was promising, certainly with help coming from finetuning flags in Llama.cpp (big shoutout to Georgi Gerganov, luv your work!) that allows me to split up the 35B AI model into 2 GPUs with differing (6GB and 22GB) VRAMs. Utilizing a…
-
AI Guide: How to Install Llama.cpp onto your Desktop PC for Local AI
June 16th, 2026 After some weeks of research, trials and errors, I managed to successfully install Llama.cpp and have it working with my AMD GPU using vulkan instead of RoCm on Linux Mint v22.3 OS. Learnt many lessons from the experience, and happy to share that here. The next thing now would be to install…
-
HomeLab 101: A Basic Setup
June 10th, 2026 This would probably be my first posting on here that would not be reposted on my FB. When one has a budget contraint that would limit your splurge on more powerful computing hardware, you will have make do with some DIY talent; and with some software integration knowhow, to put it all…
-
IT Audit like it’s 1995
FB Posting on Dec 22nd 2025 Way too hilarious to not share: Auditor: “Where do you store your backup tapes?” Customer: “We’re on AWS. Everything’s replicated across regions.” Auditor: “Yes, but where are the physical tapes?” Customer: “There… aren’t any. It’s the cloud.” Auditor: “So you don’t have backups?” Customer: Shares S3 versioning + AZ…
-
Operation Homelab – Status
FB Posting on Aug 8th 2025 Stardate 2025.08.08 – Mission Log: Operation Homelab – Status: Mostly Operational (Don’t Tell My ISP) Alright, folks, buckle up. It’s been a wild ride, fueled by YouTube tutorials, copious amounts of orange juice / soyabean milk (I don’t do caffeine), and a frankly alarming number of trial-and-error installations. Let’s…